What this blog covers
This blog explains incrementality testing and geo-lift experiments the most rigorous way to prove media actually caused sales. It defines incrementality, explains why it answers a question attribution cannot, walks through the geo-lift test design step by step, covers the pitfalls that invalidate results, and shows how to fold testing into an ongoing measurement rhythm. It closes with a self-check and the questions practitioners ask most.
Table of Contents
- The question attribution cannot answer
- What incrementality is
- Why geo-lift is the practical gold standard
- The Incrementality & Geo-Lift Test Design
- The pitfalls that invalidate a test
- Making testing a habit, not a one-off
- A test that changed a decision
- Self-check: Is your testing sound?
- Key takeaways
- Closing
- Want proof your media actually works?
The question attribution cannot answer
Attribution is good at one thing: dividing credit for a sale that happened among the touchpoints that preceded it. What it cannot tell you is whether the sale would have happened without the media at all. A retargeting ad shown to someone already walking to the checkout will be credited with the purchase by almost any attribution model, yet it may have changed nothing. The credit is real; the causation is imaginary.
Incrementality closes that gap by asking the only question that decides whether media is worth the money: what would have happened anyway? It is the referee that settles disputes between attribution models, and the foundation under any serious attribution stack. When two models disagree about a channel, an incrementality test is what tells you which to believe.
What incrementality is
Incrementality is the additional outcome sales, sign-ups, visits, branded searches that a media investment caused, over and above what would have occurred without it. It is measured by comparison: a group exposed to the media is set against a comparable group that was not, and the difference between them is the incremental effect. Everything the two groups have in common cancels out, leaving only the impact of the media itself.
That comparison is what separates incrementality from attribution. Attribution looks only at people who converted and asks which touch to thank. Incrementality looks at exposed and unexposed groups and asks how much more the exposed group did. The first can be gamed by taking credit for demand that already existed; the second cannot, because the control group carries that existing demand too.
Why geo-lift is the practical gold standard
The cleanest way to run an incrementality test at a media level is a geo-lift experiment: split the country into matched regions, run the media in some and hold it out in others, and measure the difference in the outcome. Geo-lift has two advantages that make it the practical choice for most brands. It does not depend on user-level tracking, so it survives the loss of cookies and works across offline outcomes like store sales. And it is straightforward to set up, because it works with the media you already buy. We cover the enterprise version of this in depth in incrementality at scale: designing geo experiments.
Geo-lift trades some precision for that robustness; regions are fewer and less alike than individual users, so the analysis needs care—but for proving that a channel or campaign genuinely drove business, it is hard to beat. It gives a causal number a finance team can trust, without asking the impossible of a privacy-constrained tracking environment.
The Incrementality & Geo-Lift Test Design
A geo-lift test that survives scrutiny follows four steps, each of which protects the result.
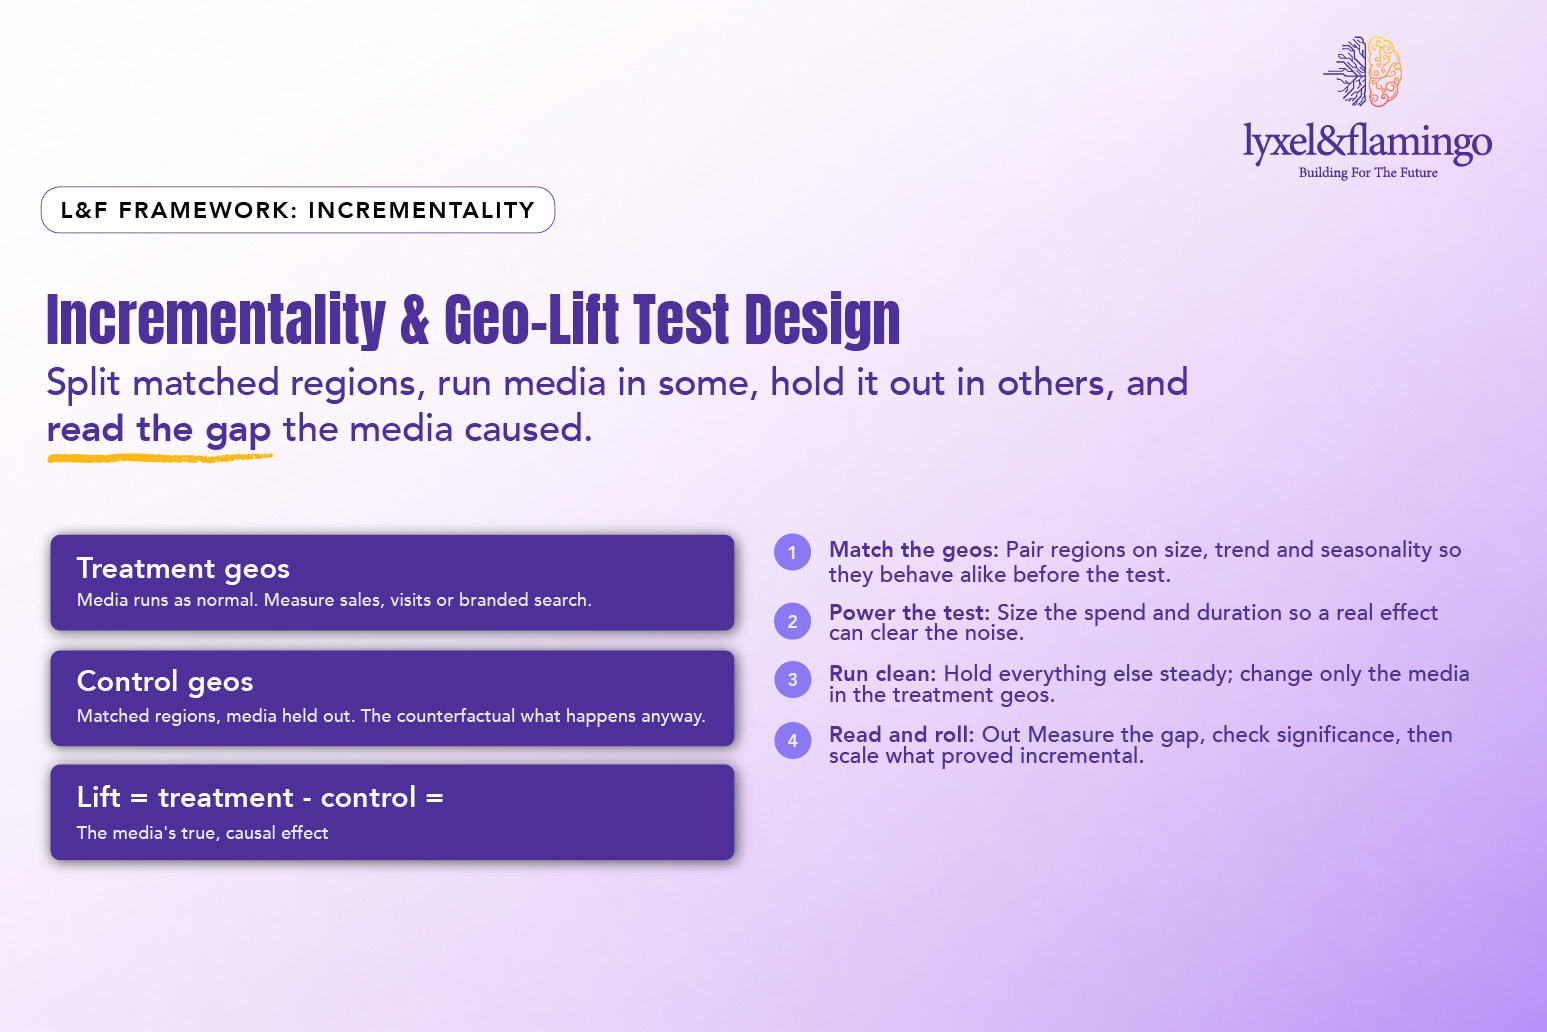
Framework: Incrementality & Geo-Lift Test Design treatment minus control equals the true effect.
The first step is to match the geos. Pair regions on size, historical sales trend, and seasonality so that, before the test, they move together; the closer the match, the cleaner the read. The second is to power the test: size the spend and the duration so that a real effect can clear the natural noise in the data, since a test too small or too short will show nothing, whether or not the media works. The third is to run a clean hold everything else steady and change only the media in the treatment geos, so that any divergence can be attributed to the media rather than to a promotion or a price change that crept in. The fourth is to read and roll out: measure the gap between treatment and control, check it is statistically significant rather than chance, and then scale what proved incremental. The gap is the true, causal effect of the media – the number worth planning on.
The pitfalls that invalidate a test
Incrementality tests are only as good as their design, and a few common mistakes quietly invalidate the result. Poorly matched geos are the most frequent: if the treatment and control regions were already diverging before the test, the difference afterwards means nothing.
An underpowered test too little spend, too short a window, too few regions cannot detect a real effect and produces a false negative that gets read as proof the media does not work.
Contamination is another: a national promotion, a PR event, or spillover from media that leaks into the control regions all blur the comparison.
And reading the result too early, before the effect has built and the numbers have stabilised, turns a signal into noise. A test that names its assumptions, powers itself properly and stays clean is one whose result deserves the weight a causal number carries.
Making testing a habit, not a one-off
Incrementality is powerful but not free, so the aim is to use it surgically rather than constantly. A practical rhythm is to run a test each quarter on a major channel or a big spending decision, and to use the results to calibrate the attribution and mix models that run continuously.
Over time, this builds a library of causal reads that keeps the everyday measurement honest: when a model claims a channel is driving sales, there is a recent experiment to check it against. Testing becomes less an occasional project and more a standing discipline that steadily raises the trustworthiness of every other number.
A test that changed a decision
The value of incrementality is clearest when it overturns what attribution assumed. For IndiGo, a brand-control approach the experimental method, holding brand media out of matched conditions proved 48% incremental sales at the same ROAS.
That is a number no attribution model could have produced, because the value was causal and partly brand-driven, and only a controlled comparison could isolate it. The result changed how the brand budget was defended: it was no longer a matter of faith that the brand work was contributing, but a measured fact.
That is what a well-designed incrementality test buys a decision made on evidence rather than assumption.
Self-check: Is your testing sound?
Score your own approach one point per yes:
- You measure incrementality, not just attribution, on major bets.
- Geo-lift tests match regions on size, trend, and seasonality.
- Tests are powered enough by spend, duration, and regions to detect a real effect.
- You hold everything else steady so only the media varies.
- Results are checked for statistical significance before they are believed.
- A test runs at least each quarter on a major channel or decision.
- Test results calibrate your ongoing attribution and mix models.
Five or more and your testing is sound. Three or fewer and your causal reads may not survive scrutiny.
Key takeaways
- Attribution divides credit for sales that happened; incrementality asks whether they would have happened anyway.
- Incrementality is measured by comparing an exposed group against a comparable unexposed control.
- Geo-lift is the practical gold standard—it needs no user tracking and works across offline outcomes.
- A sound test matches geos, powers itself, runs clean, and checks significance before believing the result.
- Run tests each quarter on major bets and use them to calibrate the models that run continuously.
Closing
Most measurement debates come down to one unanswered question: did the media actually cause the result, or just get credited for it. Incrementality is how a team stops arguing and finds out.
A geo-lift test takes effort to design and patience to read, but it produces the one thing attribution cannot: proof. For the decisions that move real money, that proof is worth the wait, because it replaces a confident guess with a number the whole business can stand behind.
Want proof your media actually works?
L&F designs incrementality and geo-lift tests matched, powered, and clean so you can prove which media drives sales for consumer brands across India and worldwide. We will build the experiment and read it honestly. Talk to L&F about incrementality and settle the question of attribution only starts.
Frequently Asked Questions
Incrementality testing measures the additional outcome sales, sign-ups, visits that a media investment caused, over and above what would have happened without it. It works by comparing a group exposed to the media against a comparable group that was not; the difference between them is the incremental effect. It answers the causal question attribution cannot: whether the media actually drove the result, or was simply credited for a result that would have occurred anyway.
Attribution looks only at people who converted and divides credit among the touchpoints that preceded the sale. Incrementality compares exposed and unexposed groups and measures how much more the exposed group did. Attribution can be fooled into crediting demand that already existed a retargeting ad shown to someone already buying. Incrementality cannot, because the control group carries that existing demand too, so it cancels out and only the media's true effect remains.
A geo-lift test is an incrementality experiment run at the regional level: you split the country into matched regions, run the media in some (treatment) and hold it out of others (control), and measure the difference in the outcome. It is the practical gold standard for media-level incrementality because it does not depend on user-level tracking so it survives cookie loss and works for offline outcomes like store sales and it uses the media you already buy.
Four things protect the result. Match the treatment and control regions on size, historical sales trend and seasonality so they move together before the test. Power the test enough spend, duration and regions to detect a real effect above the noise. Run clean hold everything else steady so only the media varies. And read it properly check the gap between treatment and control is statistically significant before acting. Skip any of these and the result may be meaningless.
Often the test was underpowered rather than the media being ineffective. Too little spend, too short a window, or too few regions can leave a real effect buried in the noise, producing a false negative. Other causes are poorly matched geos that were already diverging, contamination from a national promotion or spillover into the control, or reading the result before the effect had built. A no-effect result is only meaningful if the test was designed well enough to detect one.
Use them surgically typically at least once a quarter on a major channel or a big spending decision, and whenever you are about to make a large allocation change. The goal is not to test everything constantly, which is impractical, but to keep a recent causal read on your biggest bets and to calibrate the attribution and mix models you run continuously. One well-designed test per quarter keeps the whole measurement system honest for most brands.
Yes, that is one of its main advantages. Geo-lift tests operate at the regional level and compare matched areas rather than individual users, so they do not rely on cookies or cross-device identity. This makes incrementality one of the few measurement methods that has become more valuable, not less, as privacy changes have eroded user-level tracking. It also lets you measure outcomes that user tracking never reached, such as offline store sales.